Zyphora Zyphora

7 Best AI Inference Server Manufacturers for Global Buyers?

Time:2026-10-24 Author:Aria
0%

Choosing an ai inference server manufacturer now means examining more than processor speed. Buyers must assess latency, memory capacity, software support, power draw, and regional service coverage.

The market is expanding quickly. IDC reported that global AI infrastructure spending reached an estimated $154 billion in 2024. Its forecast also suggests continued growth through 2028. Stanford University’s AI Index 2025 found that GPT-3.5-level inference costs fell more than 280 times between November 2022 and October 2024. That change makes efficient deployment more accessible, but it also raises expectations for response speed and operating costs.

The hardware race is not slowing.

NVIDIA CEO Jensen Huang described generative AI as “the most important platform transition in computing history.” His statement reflects a major shift from model training toward daily inference workloads. In a busy contact center, thousands of short requests can create steadier pressure than one large training run. Cooling design matters. So does predictable firmware support.

This guide compares seven leading manufacturers for global buyers. It considers accelerator compatibility, server configurations, deployment flexibility, energy efficiency, warranty coverage, and partner networks. The ranking is useful, but not absolute. A cloud provider may value dense GPU scaling, while a hospital may prioritize local support and data control.

No manufacturer wins every workload. Some published performance figures also depend heavily on software tuning and test conditions. That detail is easy to overlook. Readers should verify current specifications, regional availability, and total ownership costs before purchasing.
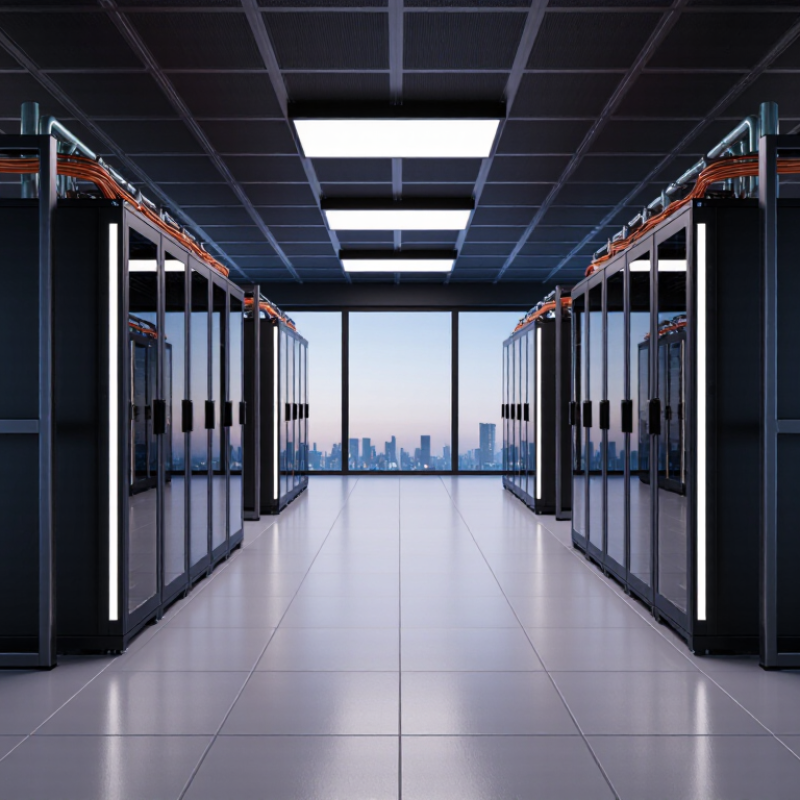
7 Best AI Inference Server Manufacturers for Global Buyers?

What Makes an AI Inference Server Manufacturer Suitable for Global Buyers

What Makes an AI Inference Server Manufacturer Suitable for Global Buyers

Global buyers need more than a fast accelerator. They need predictable performance across different operating environments. An experienced manufacturer should explain throughput, latency, power draw, and thermal limits with test conditions. Vague benchmark claims create costly surprises. Clear documentation builds trust.

Reliable manufacturers design servers for varied data centers. They consider voltage standards, rack dimensions, airflow patterns, and ambient temperatures. Effective cooling matters when inference workloads run continuously. Technicians should test components under sustained loads, not only during short demonstrations. Manufacturing quality also depends on traceable parts, firmware control, and repeatable inspection procedures.

Support must continue after delivery. Buyers may need remote diagnostics, replacement parts, installation guidance, and local service coordination. Strong manufacturers provide lifecycle plans and realistic response times. They should also explain security settings, data-handling boundaries, and relevant market certifications. Each destination has different procurement expectations. No factory gets every detail perfect. However, honest risk disclosure is more useful than polished promises. A responsive engineering team can adjust configurations for language models, vision systems, or industrial monitoring. Small details matter. A poorly fitted power cable or unclear BIOS setting can delay deployment for days. Global suitability is demonstrated through reliable shipments, verified testing, practical support, and communication that remains clear across time zones.

Core Technologies Used in Modern AI Inference Servers

For global buyers comparing seven AI inference server manufacturers, the decisive question is not chassis size. It is how efficiently each platform delivers fast, predictable responses. The Stanford AI Index Report 2024 found that querying costs for GPT-3.5-level capability fell more than 280-fold between November 2022 and October 2023. This shift favors servers designed for inference, rather than systems adapted from model training. Modern platforms combine parallel accelerators, high-bandwidth memory, PCIe fabrics, and optimized runtime software. Memory matters most. Often.

Quantization reduces model weights from 16-bit or 32-bit formats to 8-bit or 4-bit formats. This lowers memory traffic while preserving acceptable accuracy. Continuous batching keeps accelerators busy as requests arrive unevenly. KV-cache management is crucial for long-context workloads. Poor allocation can create latency spikes, even when utilization looks healthy. Buyers should request p95 and p99 latency, tokens per second, power per million tokens, and recovery data under realistic loads. Peak benchmark scores can mislead.

Thermal engineering also affects operating cost. The International Energy Agency’s Electricity 2024 analysis estimates that data-center electricity use could exceed 1,000 TWh by 2026, compared with about 460 TWh in 2022. Air cooling remains simple, but dense accelerator trays may need liquid-assisted designs. Monitoring should reveal temperature, memory errors, throttling, and model drift. Vendor claims deserve scrutiny when software versions are missing. Reproducibility is imperfect. Open benchmark scripts, clear service metrics, and replaceable components offer stronger evidence than peak throughput alone.

Seven Leading AI Inference Server Manufacturers and Their Strengths

Global buyers need more than peak accelerator speed when selecting AI inference server manufacturers. One established manufacturer focuses on dense GPU systems, delivering strong performance for large language models and image generation. Another specializes in compact edge servers, which suit factories, hospitals, and retail sites with limited space. Cooling matters there.

A third manufacturer builds energy-efficient servers for continuous workloads, helping data centers control power costs. A fourth offers flexible CPU and accelerator configurations, useful when workloads change quickly. A fifth is known for ruggedized systems that operate reliably in dusty or temperature-variable environments. Field engineers often value this practical durability more than impressive specifications.

A sixth manufacturer supports high-speed networking and multi-server inference clusters. This strength reduces delays when several models share one platform. The seventh emphasizes custom integration, including rack design, firmware tuning, and regional service support. That approach can simplify deployment for international buyers, although customization may extend delivery times.

In my experience, published benchmark scores rarely predict the full installation experience. Network congestion, software updates, and operator training can change results. Buyers should test representative models before signing large contracts. A short pilot helps.

No manufacturer is perfect. A powerful server may consume excessive electricity, while a compact unit may limit future expansion. Reliable documentation, replacement-part access, warranty response, and transparent testing deserve equal attention. These details often determine whether an inference platform remains useful after the first year.

7 Best AI Inference Server Manufacturers for Global Buyers? – Seven Leading AI Inference Server Manufacturers and Their Strengths
Manufacturer Profile Primary Market Position Typical Server Form Factors Accelerator Support Inference Workloads Key Strength Global Buyer Considerations
Profile 01 Large global enterprise-server manufacturer 1U, 2U and 4U rack servers; selected tower systems PCIe accelerator cards, integrated accelerator modules and high-memory CPU configurations Natural-language processing, recommendation systems, computer vision and enterprise analytics Broad product portfolio with strong enterprise integration Suitable for buyers requiring worldwide support, validated configurations and long product lifecycles
Profile 02 High-performance computing and data-center specialist Dense 2U and 4U rack platforms with high power capacity Multi-accelerator systems with high-speed interconnects and large memory capacity Large language model serving, scientific inference, simulation and batch AI processing High compute density and strong thermal engineering Best for data centers with sufficient power, cooling and rack infrastructure
Profile 03 Edge-computing and compact AI server manufacturer Short-depth rack, compact 1U and ruggedized edge systems Low-profile accelerator cards, embedded modules and CPU-based inference options Industrial inspection, retail analytics, video processing and private edge AI Compact deployment and reduced network dependency Useful where space, latency, noise and local data processing are important
Profile 04 Customizable server and integration specialist Configurable 1U, 2U, 4U and multi-node rack systems Flexible support for current PCIe accelerators, high-speed networking and custom storage layouts Private cloud inference, enterprise model serving and specialized AI applications Configuration flexibility and faster adaptation to project requirements Buyers should verify firmware compatibility, validation scope and regional service coverage
Profile 05 Cloud-oriented data-center infrastructure provider High-density multi-node rack servers and disaggregated infrastructure Multi-accelerator nodes, high-bandwidth memory options and advanced fabric connectivity Real-time generative AI, model APIs, search ranking and large-scale recommendation Scalability for growing inference demand Well suited to centralized deployments that prioritize automation and fleet management
Profile 06 Energy-efficient and sustainability-focused server manufacturer Efficient 1U and 2U rack systems with optimized airflow designs CPU inference, moderate accelerator configurations and power-managed accelerator nodes Speech recognition, document processing, cybersecurity and business intelligence Balanced performance per watt and manageable operating cost Appropriate for facilities with power limits or strong energy-efficiency targets
Profile 07 Regional enterprise and value-focused server supplier Standard 1U and 2U rack systems with practical expansion options Common PCIe accelerator configurations and high-core-count CPU platforms Small and medium-scale AI inference, surveillance, ERP analytics and automation Competitive acquisition cost and straightforward deployment Before purchase, confirm local inventory, spare-parts availability, warranty terms and technical support
Evaluation criteria include deployment form factor, accelerator expandability, workload suitability, scalability, energy efficiency, serviceability and international support capability.

How to Compare Performance, Scalability, Support, and Total Cost

Choosing among the seven best AI inference server manufacturers requires more than comparing processor names. Performance should be measured with real workloads, not only advertised peak figures. Track tokens per second, first-token latency, batch efficiency, and response consistency. Test both small language models and larger models under simultaneous requests. A fast result with one user may collapse during a busy afternoon.

Scalability deserves equal attention. Examine accelerator expansion, memory capacity, network bandwidth, and compatibility with existing orchestration systems. Modular servers can reduce disruption as demand grows. However, expansion paths are sometimes limited by power, cooling, or rack space. A practical pilot should run for several days, including failure recovery and uneven traffic. Clean benchmarks can still mislead.

Support quality often separates similar manufacturers. Look for documented firmware updates, remote diagnostics, spare-parts availability, and engineers who understand inference software. Service coverage across time zones matters for global buyers. Compare response targets, warranty terms, installation assistance, and escalation procedures. Ask for references from deployments with similar traffic patterns. Vague answers are warning signs.

Total cost includes much more than the purchase invoice. Calculate electricity, cooling, software licenses, maintenance, connectivity, downtime, and staff training over three to five years. A lower-priced server may consume more power every hour. Conversely, premium hardware may be wasteful for modest demand. I would record assumptions openly, because cost models are rarely perfect. Procurement teams should also review security certifications, data-handling practices, and regional compliance documents before signing.

AI Inference Server Evaluation Priorities for Global Buyers

The chart uses a 100-point purchasing model based on commonly measurable enterprise criteria: inference performance, scalability, operational support, energy efficiency, and three-year total cost of ownership. Higher values indicate greater importance in a global procurement decision.

Selecting the Right AI Inference Server for Different Business Needs

Selecting the Right AI Inference Server for Different Business Needs

Choosing among the seven best AI inference server manufacturers requires matching hardware to workload, not chasing peak specifications. A retail platform may need low-latency responses during checkout. A research team may value flexible model support and rapid reconfiguration. The Stanford AI Index 2025 reports that inference costs for GPT-3.5-level performance fell more than 280-fold between November 2022 and October 2024. This shift makes efficiency important, but it does not make every server suitable.

Check throughput, memory capacity, networking, cooling, and software compatibility. A medical imaging provider may prioritize predictable latency and strong data isolation. A global application may need efficient scaling across regions. MLPerf Inference results show that performance varies significantly by model, batch size, and response-latency target. Therefore, one impressive benchmark can mislead. Test a server with your own prompts, traffic patterns, and peak-hour conditions. A perfect choice rarely exists. I would also question optimistic power estimates, because real workloads often behave differently.

Tips: Request a 24-hour pilot with production-like data. Measure tokens per second, first-response latency, power use, and failure recovery. Ask for three-year operating costs, including maintenance and cooling. Leave headroom for larger models. Small savings today may create expensive capacity problems later. Keep human review in the evaluation process; technical scores alone cannot measure business risk, user experience, or operational simplicity.

FAQS

What should global buyers check before choosing an AI inference server manufacturer?

Check performance data, cooling design, power use, testing methods, documentation, and long-term support. Clear evidence matters.

How should server performance be tested?

Test real workloads, including language models, vision tasks, and multiple simultaneous requests. Measure tokens per second, first-token latency, batch efficiency, and response consistency. Peak results can mislead.

Why are thermal conditions important for inference servers?

Continuous inference creates sustained heat, unlike short demonstrations. Manufacturers should test servers under extended loads and different ambient temperatures. Cooling failures can reduce performance.

What physical data-center details should buyers confirm?

Confirm voltage standards, rack dimensions, airflow direction, cable placement, and available cooling capacity. A poorly fitted power cable can delay installation for days.

How can buyers evaluate scalability?

Review memory capacity, accelerator expansion, network bandwidth, and orchestration compatibility. Also check power and rack limits. Expansion is not always simple.

What support should a reliable manufacturer provide after delivery?

Support may include remote diagnostics, spare parts, installation guidance, firmware updates, and local coordination. Ask about response targets and escalation procedures. Promises need evidence.

How should buyers calculate total cost?

Include hardware, electricity, cooling, software, connectivity, maintenance, training, and possible downtime. Review costs across three to five years. Cheap hardware may cost more later.

Why is a pilot deployment useful?

A several-day pilot can reveal network congestion, recovery problems, uneven traffic, and software compatibility issues. Use representative models and realistic user demand. Short tests are imperfect.

What security and compliance questions should buyers ask?

Ask how data is handled, which security settings are available, and what regional documents exist. Requirements differ by destination. Do not assume one certificate solves everything.

Can any manufacturer meet every global requirement perfectly?

Probably not. Buyers should value honest risk disclosure, traceable parts, repeatable inspections, and clear communication. I might overvalue specifications sometimes. Deployment details often matter more.

Conclusion

Choosing the right ai inference server manufacturer is essential for organizations that need fast, reliable, and scalable AI deployment across global markets. A suitable manufacturer should offer strong engineering capabilities, international compliance awareness, flexible configuration options, dependable supply, and responsive technical support. Modern AI inference servers commonly rely on advanced accelerators, optimized processor architectures, high-speed memory, efficient networking, containerized software, and intelligent workload management to deliver consistent performance for real-time applications.

This overview examines seven types of leading manufacturers and the strengths they typically provide, including computing performance, energy efficiency, system integration, scalability, customization, and service coverage. It also explains how buyers can compare throughput, latency, expansion potential, warranty support, software compatibility, and total cost of ownership. By matching these factors with specific requirements—such as cloud services, enterprise analytics, edge computing, research, or large-scale automation—businesses can select an inference platform that balances performance, budget, operational reliability, and long-term growth.
Aria

Aria

Aria is a dedicated marketing professional with a deep passion for innovative strategies and a keen understanding of our company's product offerings. With a wealth of experience in the industry, Aria excels at crafting engaging content that highlights the unique features and benefits of our......